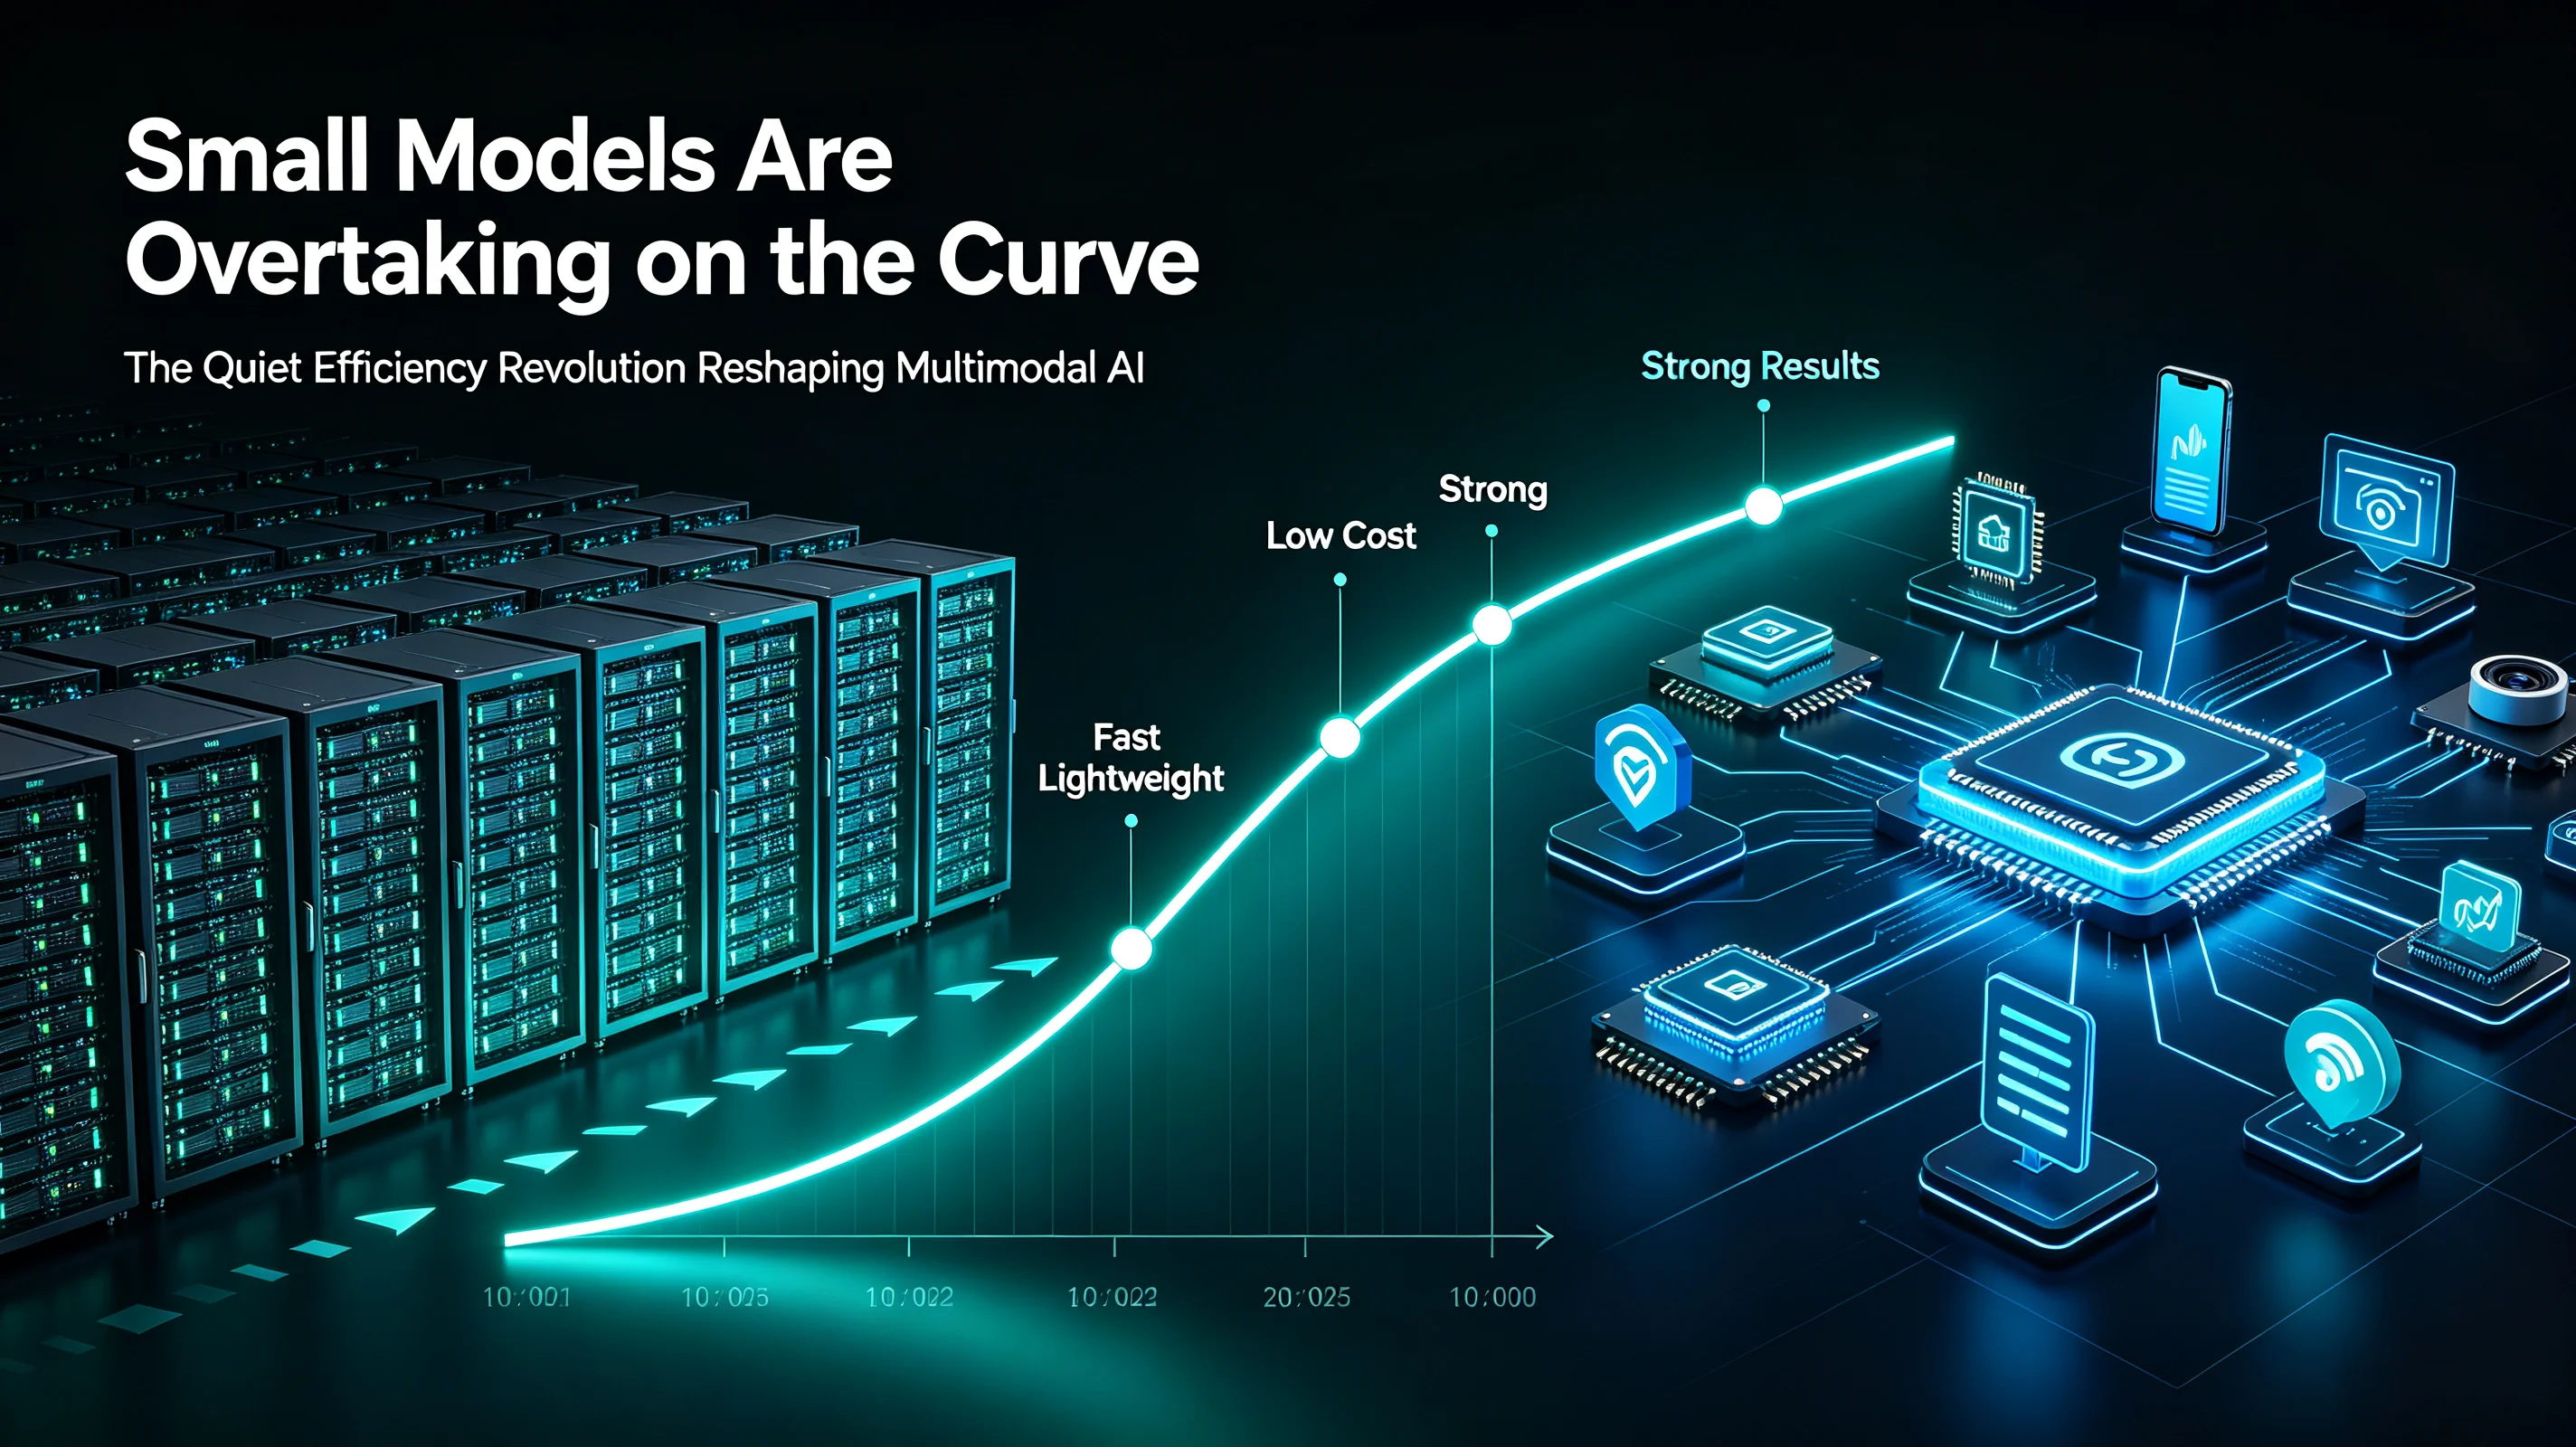
Remember two years ago, when the industry was still debating whether “bigger is the only way forward”? By mid-2026, the answer has become quite clear — not necessarily.
A group of seemingly “compact” multimodal models is quietly approaching, and in some critical tasks even matching, the performance of frontier models with hundreds of billions of parameters — while using far fewer parameters and much lower inference costs. These models are no longer just “good enough.” They are starting to deliver genuinely competitive results in real-world business scenarios. The shift has arrived faster, and more quietly, than most people expected.
From “Stacking Parameters” to “Prioritizing Efficiency”: When Did the Wind Change?
From 2024 to 2025, the dominant narrative revolved around “bigger, stronger, more expensive.” Closed-source frontier models kept setting new benchmarks, while the open-source camp raced to catch up in scale. Yet after entering 2026, another thread became increasingly clear: in a large number of practical use cases, what truly determines user experience and cost is not peak capability, but effective output per unit of compute.
Efficient multimodal models hit exactly this pain point. They either adopt Mixture-of-Experts (MoE) architectures — large total parameter counts but only a small portion activated during each inference — or use distillation, specialized post-training, and architectural innovations to extract higher task performance from limited parameters. The result: models become lighter, faster, and cheaper, while already being “good enough or even better” on visual understanding, document processing, tool calling, and simple agentic tasks.
This is not merely a technical iteration. It represents a shift in value judgment: from “getting as close as possible to the theoretical optimum” to “achieving sufficiently good performance under real-world constraints.”
Key Players: Who Is Turning “Small” into a Competitive Advantage?
The efficiency track currently features three main categories of active players.
The first category consists of high cost-performance MoE multimodal models. GLM-5.3-Flash, with roughly 320B total parameters and 18B activated, natively supports image and video input. On coding and agent-related benchmarks it already approaches some frontier models, yet costs only a fraction of comparable large models. DeepSeek V4.1 Flash pushes activated parameters even lower (approximately 8B during prefill and 16B during decoding), while retaining native vision capabilities and a million-token context window, delivering strong results on tasks such as Terminal-Bench. Qwen’s Flash series continues to set new records for its size class on multimodal understanding, OCR, and chart-related tasks.
The second category comprises ultra-small models truly designed for edge and on-device deployment. Liquid AI’s LFM2.5 series (ranging from 230 million to 2.6 billion parameters) frequently outperforms models three to four times larger on data extraction, instruction following, and tool use, and can already run complete agent workflows on phones or even Raspberry Pi devices. Models such as MiniCPM-V, SmolVLM, and VisionPsy-Nano (around 0.5B) have demonstrated the viability of “small but precise” approaches on document understanding and visual question answering. Google’s Gemma-4 MoE variants are also attempting to pack multimodal capabilities into consumer-grade hardware.
The third category sits between the two: mid-sized efficient models. They neither severely constrain capability boundaries like the ultra-small models nor chase extreme scale. Instead, they seek a practical balance among performance, latency, and deployment cost, making them well-suited as primary models for high-frequency internal enterprise calls.
Common traits across these models include treating multimodal ability as a core capability from the pre-training stage rather than an add-on, supporting significantly longer context windows, and offering a much higher proportion of open weights that facilitate secondary development and local deployment.
Is the Performance Gap Really Closing?
Objectively speaking, the gap has not disappeared, but it is narrowing rapidly and showing clear task differentiation.
On the hardest general reasoning, ultra-long chain planning, and highly creative generation tasks, top closed-source frontier models still hold the lead. However, across a large volume of high-frequency, structured or semi-structured tasks — document information extraction, chart interpretation, interface understanding, simple tool calling, and multi-step but relatively patterned agent workflows — efficient models have already come close enough, and in cost-performance terms often pull ahead.
Benchmark data supports this picture. The gap between some leading open efficient models and the frontier on composite intelligence indices has shrunk from double digits a year ago to single digits. On certain agentic tasks and multimodal understanding evaluations, low-activation-parameter models frequently rank in the top tier. More importantly, the “perceived gap” in real business use is often smaller than pure benchmark differences, because many tasks do not require models to exercise their full theoretical capability.
Progress on the edge is especially striking. Running multimodal models on phones used to be largely demonstrative; now practical latency and power consumption levels are beginning to appear. This means privacy-sensitive, network-unstable, or offline-required scenarios finally have genuinely usable options.
Why the Acceleration Now?
The efficiency revolution did not appear overnight. It results from the convergence of several factors.
First, training and post-training techniques have matured. High-quality data filtering, knowledge distillation, reinforcement learning conducted inside real agent environments, and early compression of vision encoders all enable small models to allocate limited parameters to more critical capabilities.
Second, architectural innovation has advanced. MoE has moved from “proof of concept” to a stably trainable and deployable engineering solution. Hybrid attention mechanisms (combining short convolutions, linear attention, and a limited number of standard attention layers) have significantly reduced inference costs. Context-extension techniques have also made long-document processing no longer the exclusive domain of large models.
Third, hardware and deployment ecosystems have caught up. Improvements in consumer GPUs, phone NPUs, and edge chips, combined with optimizations in inference frameworks such as llama.cpp, MLX, vLLM, and ONNX, have made it possible for small models to actually “run well and run fast.”
Finally, market demand has forced the issue. Enterprises are no longer satisfied with “using the most expensive model to prove AI can do it.” They have begun seriously calculating unit output cost, latency, and privacy compliance. High-frequency call scenarios are extremely price-sensitive, creating substantial room for efficient models to thrive.
What Does This Mean for Enterprises?
Selection logic is undergoing a substantive change.
Previously, many defaulted to “use the largest available model if possible.” Now teams are asking three more practical questions: Does this task truly require the strongest model? Can local or edge deployment simultaneously satisfy privacy and cost requirements? Under high concurrency, is cost-performance more important than peak capability?
As a result, more systems are adopting layered architectures: the most complex decisions and creative tasks are handled by frontier large models, while everyday high-frequency multimodal understanding, information processing, and tool calling are delegated to efficient mid- and small-sized models. This division both controls costs and improves overall response speed.
The vitality of the open-source ecosystem further amplifies the trend. Developers can rapidly fine-tune, distill, or compose versions better suited to their own business on top of these efficient models, without starting from scratch or relying entirely on closed-source APIs each time.
Challenges Remain
Of course, the efficiency path is not without trade-offs.
Small models still face natural limitations in knowledge breadth and depth of complex reasoning; performance can drop noticeably when encountering tasks outside their training distribution. Multimodal consistency, hallucination control, and deep cross-modal reasoning remain areas requiring continuous improvement. Although MoE models activate few parameters, their large total parameter counts still impose certain pressures on storage and loading. Edge models must repeatedly balance accuracy, speed, and power consumption.
In addition, the gap between benchmarks and real business use persists. Some models shine on public evaluations but may perform only averagely on long-tail scenarios or domain-specific data. Establishing evaluation systems that more closely reflect actual usage is itself a problem the industry still needs to solve.
Closing Thoughts: Efficiency Is Becoming the New Competitive Edge
The essence of this shift is not that small models have defeated large ones, but that “efficiency thinking” is becoming mainstream. AI is moving from a pure parameter arms race toward a stage of pursuing higher unit output under real constraints.
In the coming years, the most successful AI systems are likely to be those that are not single models handling every task, but layered collaborations in which large models handle high-difficulty decisions, efficient models manage high-frequency execution, and edge models cover local and privacy-sensitive scenarios. Whoever designs this collaboration better will gain advantages in cost, speed, and user experience.
The rise of small models appears on the surface as diversification of technical routes; at a deeper level, it signals that AI applications are entering a more mature and pragmatic phase. When “good enough and economical” becomes an important evaluation criterion, the entire industry’s direction of innovation will adjust accordingly.
A quiet yet profound efficiency revolution is underway. And its impact is only just beginning to show.
Transparency Disclosure: Content here is for informational guidance. This publication maintains editorial independence, though some links may generate affiliate revenue. For copyright inquiries or content removal, please reach out to our desk.